AI Automation
From Paper Piles to Connected AI Workflows: Digitising the Work That Still Lives on Desks
How mid-market teams turn document chaos into structured data that flows into CRM, voice, and ops systems — without a multi-year digital transformation programme.
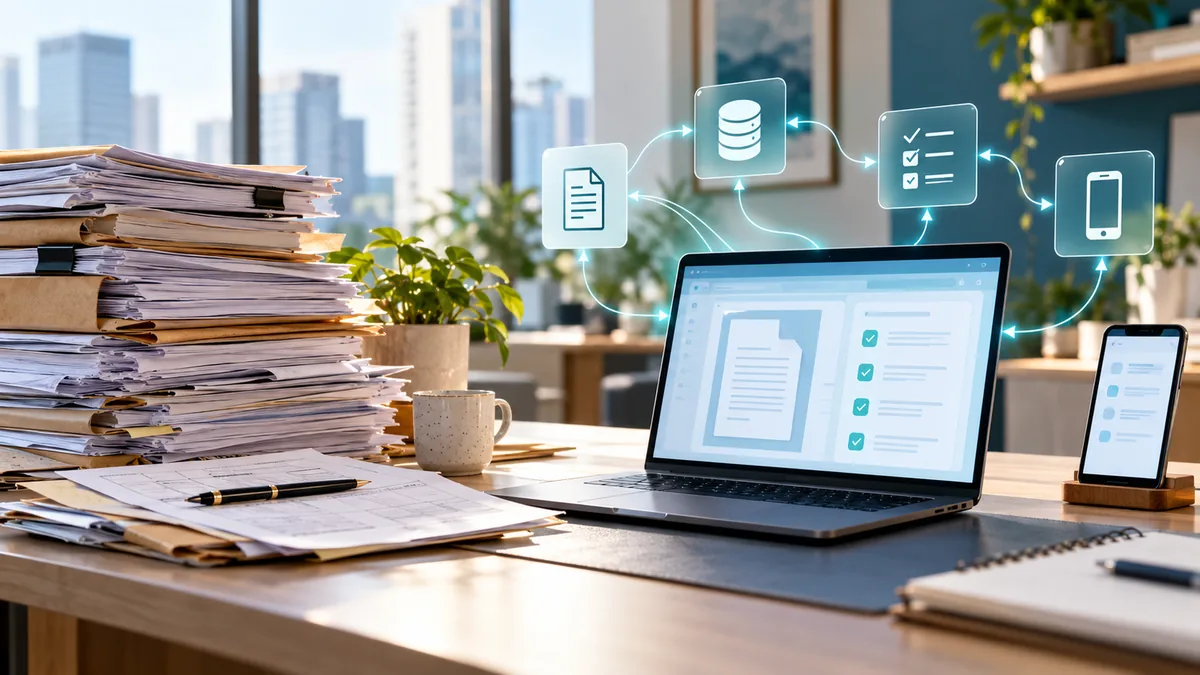
Walk into most mid-market offices in Palm Beach or Broward and you will still find the same scene: stacks of intake forms, invoices, contracts, and handwritten notes sitting next to people who already live in Salesforce, HubSpot, or a legacy ERP. The systems are digital. The work that feeds them is not. That gap — paper and PDFs on one side, structured records on the other — is where hours disappear and errors compound.
AI automation does not mean scanning everything into a shared drive and calling it done. It means extracting the fields that matter, validating them, routing exceptions to a human, and writing clean data into the systems your teams already use. Done well, the paper pile becomes a signal stream. Done badly, you get a more expensive filing cabinet.
The real cost of desk-bound documents
Document work is rarely measured as a line item. It hides inside “admin time,” overtime, and delayed cycle times. A claims packet that sits three days before someone keys it in is not a storage problem — it is a cash-flow and customer-experience problem. An invoice that is re-typed into accounting is a double-entry tax paid on every vendor relationship.
- Re-keying: the same data entered twice, with a third pass when the two versions disagree.
- Search failure: the answer exists in a binder or email attachment nobody can find in under ten minutes.
- Handoff lag: work waits for the person who “knows how to process these.”
- Audit risk: incomplete trails when a regulator or customer asks what happened and when.
If a process touches more than a few hundred documents a month, the unit economics of manual handling almost never beat a well-scoped automation — provided you automate extraction and routing, not judgement.
What “connected” actually means
A connected document workflow has four layers. Capture turns paper, email attachments, and portal uploads into machine-readable input. Understanding extracts entities, amounts, dates, parties, and intent — not just OCR text. Decisioning applies rules and confidence thresholds: auto-post the clear cases, queue the rest. Integration writes results into CRM, ERP, ticketing, or a voice follow-up queue so the next human step starts with context, not a blank screen.
The glowing hub in the middle of that architecture is not a single model. It is orchestration: models for extraction, rules for policy, humans for exceptions, and APIs for systems of record. Treat any one of those as optional and the programme stalls at the pilot stage.
Start with one high-volume document type
Do not boil the ocean. Pick one document family with volume, a stable layout or a manageable set of variants, and a clear downstream system — vendor invoices into AP, patient intake into the EHR or CRM, loan packages into underwriting, service tickets with photo attachments into field ops. Measure baseline cycle time, error rate, and cost per document before you touch a model.
Define success as a percentage auto-processed end to end with no human touch, plus a median review time for the exception queue. If you cannot state those two numbers, you are not ready to build — you are still discovering.
Human-in-the-loop is the product, not the apology
Every serious document automation ships with a review UI: original image, extracted fields, confidence scores, and one-click correct-and-release. Reviewers should finish a typical exception in seconds, not minutes. Capture every override as training and evaluation signal so the auto-pass rate rises over time without expanding headcount.
Cap the queue. If exceptions climb above your planned band, stop expanding volume and fix extraction or upstream form design. An unbounded review backlog is just the paper pile with better lighting.
Wire documents into the rest of the stack
Extraction alone is a feature. Value shows up when the structured result triggers the next action: a CRM record updated, a workflow ticket opened, an agent tasked, a voice callback scheduled. For South Florida operators building that connective tissue, four HLS AI Solutions engagements map directly onto the work:
- AI Automation — the capture, extraction, and continuous processing layer that turns documents into structured events.
- Workflow Automation — the routing, retries, and handoffs between intake, review, and systems of record.
- CRM Integration — the write-back path so sales and service teams see clean records without re-keying.
- AI Agents — the decision layer that triages ambiguous packets, classifies intent, and escalates only when needed.
- Voice AI — the outbound or inbound follow-up when a document is incomplete and a human conversation closes the gap faster than another form.
- AI Implementation — the production path — security, observability, rollout, and operator enablement so the pilot survives contact with real volume.
Related field notes worth reading alongside this one:
- Designing Human-in-the-Loop Workflows That Scale — how to keep reviewers only on the uncertain cases.
- Workflow Automation Across Salesforce, HubSpot and Your Legacy Stack — hardening the seams where document data actually lands.
- AI Automation for SEO — another high-volume, pattern-based automation domain with the same capacity logic.
- From Pilot to Production: The 80% of AI Work Nobody Talks About — what it takes to move document automation past the demo.
Governance without freezing delivery
Documents often carry PII, financials, or regulated content. Inventory which document types touch which data classes. Restrict model and storage access to least privilege. Log every extraction and human override. Prefer on-path redaction for fields the downstream system does not need. A lightweight inventory, approval gate, and audit log beat a 40-page policy nobody follows — the same mid-market governance pattern we use across AI programmes.
A 30-day sequence that ships
- Week 1: pick one document type, baseline volume/cost/errors, map the destination system and owners.
- Week 2: stand up capture + extraction on a representative sample; define confidence thresholds and kill criteria.
- Week 3: build the review UI and write-back integration; run shadow mode against live volume.
- Week 4: flip auto-post for high-confidence cases; measure auto-rate, review time, and error escapes; decide expand, fix, or kill.
If week four cannot show a credible path to a majority of documents clearing without a human, do not scale the programme — fix the document design, the training set, or the process itself first.
The takeaway for South Florida operators
Paper and PDFs are not a nostalgia problem. They are an integration problem. The teams that win treat documents as first-class inputs to AI automation — extracted, decided, written into CRM and ops systems, with humans only on the edge cases. That is how a Boca Raton or Fort Lauderdale operation absorbs growth without hiring another row of data-entry seats.
If your desks still feed your systems by hand, start with one document type and a 30-day kill criterion. The stack — automation, workflow, CRM, agents, and implementation discipline — is already how we ship this class of work for Palm Beach and Broward clients.
For deeper context on standards and research that inform production document and process automation:
- NIST AI Risk Management Framework — the US standard for governing AI risk when systems touch operational and personal data.
- OECD AI Principles — intergovernmental standard on trustworthy AI adoption.
- McKinsey — The State of AI — annual benchmark on enterprise AI adoption and value capture.
- Harvard Business Review — Adopting AI — practical guidance on sequencing AI into operations.